Oct 8, 2026 in AI Basics
Opus 5.5 vs Fable 5.1 on Reddit, and What the Tests Show
Opus 5.5 vs Fable 5.1 compared on cost, speed and accuracy, using benchmark data, one hands-on test and what Reddit users report…
14 posts with this topic.
Opus 5.5 vs Fable 5.1 compared on cost, speed and accuracy, using benchmark data, one hands-on test and what Reddit users report…
KV cache quantization can buy longer context without new hardware. One user went from 32k to 80k. What it saves, what it…
Quantization quality loss is small at 4-bit and sharp below 3-bit. For code, one test scored the same files 13 to 16…
Quantization explained simply. What Q4, Q8 and GGUF mean, how to read a filename like Q4_K_M, and which file to download for…
The best free local AI models for October 2026, matched to 4GB through 64GB of memory by real download size, with every…
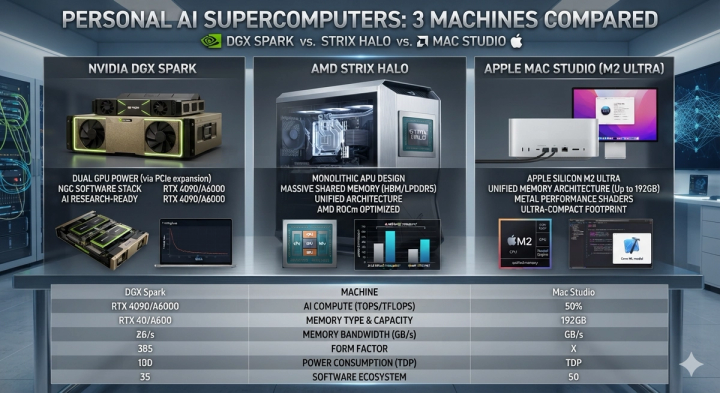
DGX Spark, Strix Halo, Mac Studio or a GPU rig? One spec, memory bandwidth, decides most of a personal AI computer's speed.…
The 2026 memory crisis is why RAM, SSDs and GPUs all got expensive. Here's what is happening to prices, why AI is…
What hardware do you need to run AI models locally? VRAM, RAM and disk decide it. Here's a sizing guide for 8GB,…
Local AI vs cloud AI compared on privacy, cost, quality, speed and convenience, with honest numbers and a simple way to decide…
Browse, download, and run local AI models using LM Studio.
The open-source C/C++ project that made running LLMs on everyday hardware possible.
A desktop app that runs open models on your machine and keeps your chats private.
The easiest way to download and run large language models on your own computer, offline.
ChatGPT, Claude and Gemini compared for coding, research, writing and everyday work, with pricing and benchmark scores to help you choose one.